103 models ran 40 real GTM tasks — forecasts, CRM audits, renewal-risk calls, executive briefs — built from live, redacted company data. Every answer was graded by deterministic code against computed ground truth. No LLM judged any response. Every score is inspectable, answer by answer.
Start with the narrative, then drill into any number. Everything links back here.
Why the benchmark exists, how 40 tasks were built from real GTM data, how deterministic grading works, and what the caveats are.
overview.html →The executive document: findings, method, archetypes, and what they mean for GTM and operations leaders. Docx with embedded charts.
06_Research/ →Every artifact and where it lives: results, tests, answers, graphs, model docs, research.
PACKAGE_GUIDE.md →Every ranking footnotes its basis: 40 tasks, deterministic rubric, no LLM judge.
The complete results matrix, color-coded cell by cell. Click any model to read its actual answers against the correct answer.
01_Results/BonuslyBench_Final_Results.html →Per-task deltas against the reference model — context for how each challenger performed relative to a familiar baseline.
01_Results/BonuslyBench_Base_Comparison.html →Leaderboard, full matrix, test difficulty, and model info — four sheets, Google-Sheets-ready.
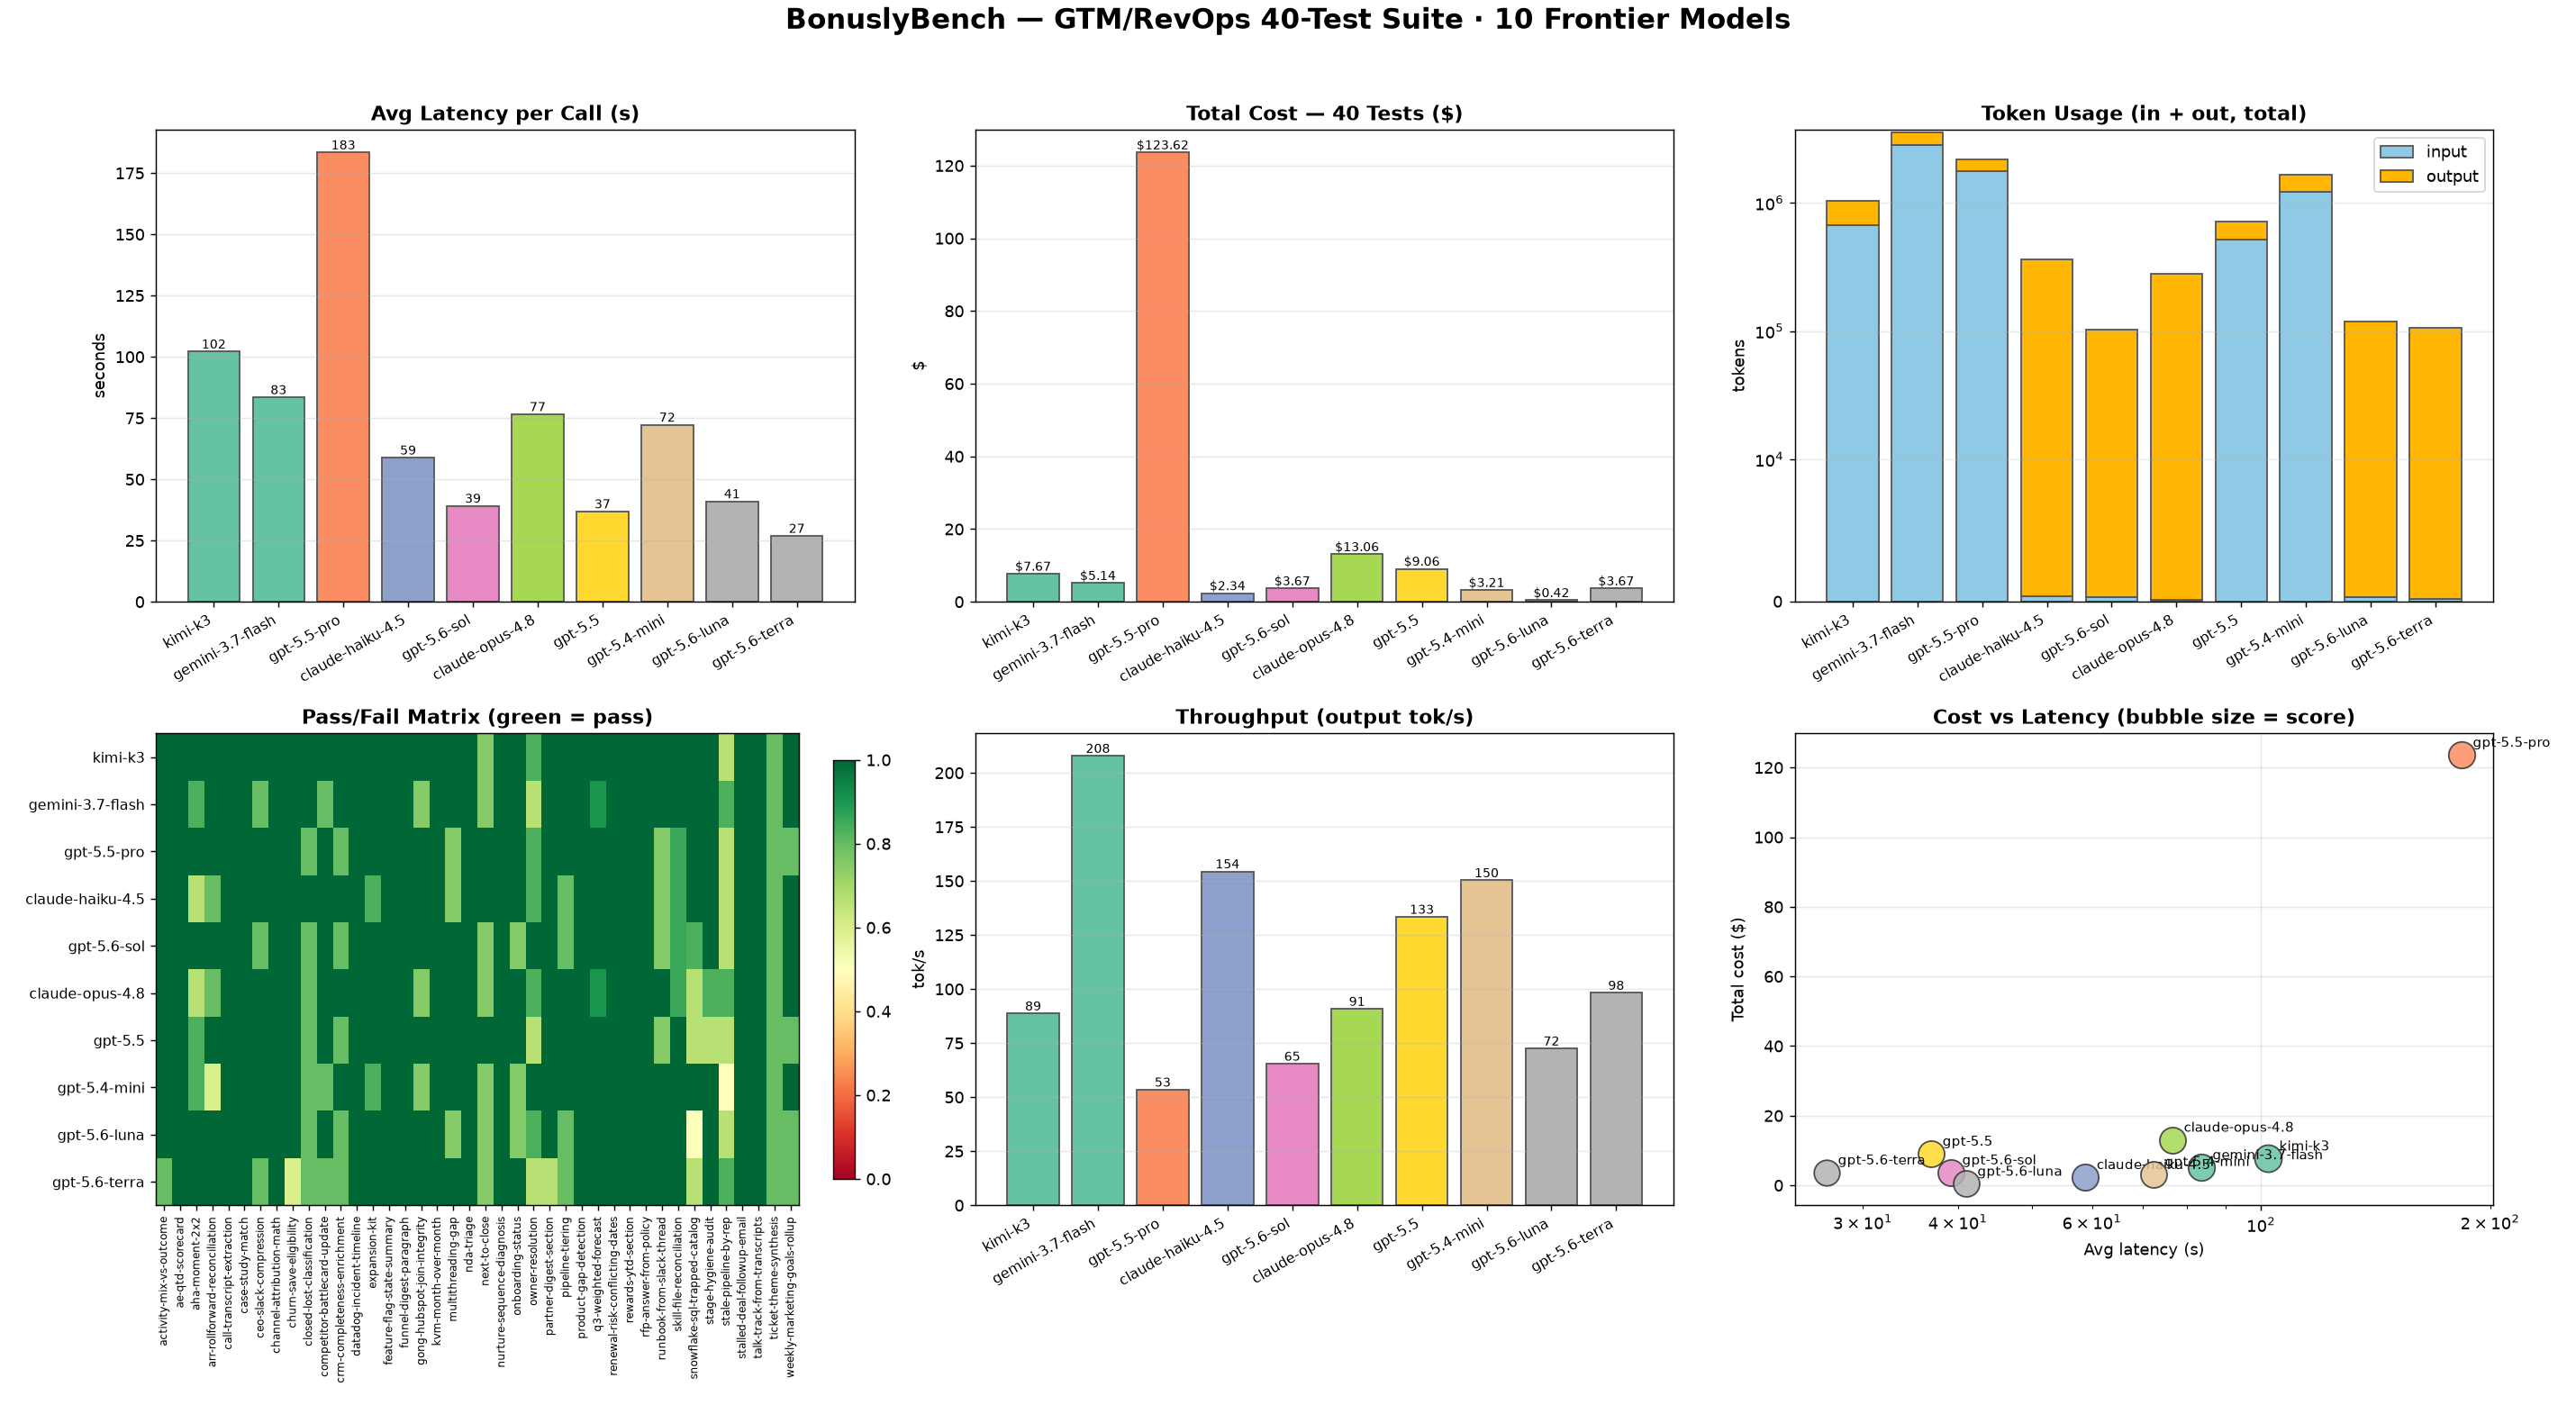
01_Results/BonuslyBench_Results.xlsx →Latency, cost, tokens, pass rates, throughput, and the value map — the visual summary of the run.
04_Graphs/ →Top five per category of work, the first five open models for teams coming from Anthropic or OpenAI, and the guardrails that matter regardless of model.
05_Models/BonuslyBench_Model_Recommendations.html →Six behavioral profiles — from complete analysts to fast communicators — plus the cost-for-value dollar map.
05_Models/BonuslyBench_Model_Archetypes.html →A ranking without evidence is not a BonuslyBench ranking. Every score below can be traced to a graded answer.
For every model and every task: the question asked, the correct answer, and the model's complete unedited response, side by side with per-check grading.
03_Answers/reviewer/index.html →All 40 tasks with their planted traps, the deterministic checks, and the grading methodology. Also as PDF.
02_Tests/ →