BonuslyBench · Behavioral Clustering · 2026-09-13

Model Archetypes — How the Models Actually Behaved

91 models with ≥20 tests, clustered on behavioral dimensions — not just scores: per-category strengths, cost, latency, fabrication events, and math-vs-prose tilt. This is an acknowledgement of observed behavior, not a recommendation. Every model links to its full answer-by-answer record in the Response Reviewer.

Use these profiles conversationally: "these models perform like this." A Complete Analyst behaves like a senior operator; a Fast Communicator writes well but stumbles on rollforward math; Capable-but-Loose models need an entity-validation guardrail. Clustering is k-means (k=6, 20 seeds) over standardized category profiles + log-cost + log-latency + fabrication rate.

The Complete Analysts

26 models
elite-accuracyfastall-around-analyst
median mean 0.949median cost $6.60median latency 49sstrongest communicationweakest data & crmfabrication events 0
Elite-accuracy, fast, all-around performers. High scores in every category with no weak flank; communication and reporting both strong. These models behave like a strong senior analyst: correct math, disciplined formatting, honest caveats.
ModelMeanCostLat
meta/muse-spark-1.10.977$2.1740s
moonshotai/kimi-k30.976$7.67102s
meta/muse-spark-1.30.973$3.0343s
anthropic/claude-opus-50.967$15.91107s
google/gemini-3.8-flash0.966$6.34117s
meta/muse-spark-1.20.964$3.6062s
qwen/qwen3.8-max-09020.962$3.88160s
z-ai/glm-5.30.960$6.86301s
anthropic/claude-opus-4.50.957$9.8390s
sakana/fugu-ultra0.957$31.55410s
openai/gpt-5.5-pro0.956$123.62183s
anthropic/claude-opus-4.70.954$10.7062s
google/gemini-3.7-flash0.953$5.1483s
openai/gpt-6-astra0.952$19.8248s
deepseek/deepseek-v4-pro-08130.947$1.85110s
anthropic/claude-haiku-4.50.944$2.3459s
qwen/qwen3.8-2.4t-a95b0.943$5.20259s
openai/gpt-5.50.941$9.0637s
openai/gpt-6-astra-pro0.941$43.5469s
openai/gpt-5.6-sol0.940$3.6739s
anthropic/claude-opus-4.80.937$13.0677s
openai/gpt-5.6-sol-pro0.937$7.9753s
openai/gpt-5.6-terra0.920$3.6727s
thinkingmachines/inkling0.916$3.1347s
openai/gpt-5.6-terra-pro0.915$7.9841s
openai/gpt-chat-latest0.908$3.77120s

The Reliable Operators

33 models
strongbudgetprose-over-math
median mean 0.923median cost $0.63median latency 83sstrongest ops & maintenanceweakest data & crmfabrication events 0
Strong, budget-priced workhorses. Slightly below the elite tier, best on ops-maintenance and routine execution, weakest on data-crm edge cases. Behavior profile: steady, cheap, occasionally thin on the hardest multi-table reconciliation.
ModelMeanCostLat
xiaomi/mimo-v2.5-pro0.974$0.69119s
z-ai/glm-5.3-flash0.968$0.28401s
tencent/hy3-preview0.968$0.5982s
z-ai/glm-5-turbo0.966$1.21141s
qwen/qwen3.8-flash0.965$0.34111s
deepseek/deepseek-v4-pro0.959$1.04328s
meituan/longcat-2.00.955$0.63245s
moonshotai/kimi-k2.7-code0.953$1.571145s
qwen/qwen3.8-27b0.953$1.63213s
nex-agi/nex-n2-mini0.945$0.061445s
minimax/minimax-m2.10.942$0.6760s
deepseek/deepseek-v4-flash-07310.939$0.0955s
poolside/laguna-s-2.10.939$0.27173s
openai/gpt-5.6-luna0.936$0.4241s
xiaomi/mimo-v2.50.932$0.2763s
meta/muse-glimmer-30b0.925$0.9898s
minimax/minimax-m2.50.923$0.44594s
inclusionai/ling-3.0-flash0.919$0.0649s
minimax/minimax-m20.914$1.1959s
ibm-granite/granite-4.2-8b0.912$0.36310s
tencent/hy4-preview0.906$1.731548s
aion-labs/aion-3.00.904$3.54913s
bytedance-seed/seed-2.0-mini0.900$0.12118s
google/gemma-4-31b-it0.890$0.16516s
bytedance-seed/seed-1.60.889$0.71116s
minimax/minimax-m30.878$0.622415s
aion-labs/aion-3.0-mini0.874$1.29194s
arcee-ai/trinity-large-thinking0.873$0.6874s
deepseek/deepseek-v3.20.864$0.97220s
poolside/laguna-xs-2.10.854$0.36623s
aion-labs/aion-2.00.853$0.76125s
thinkingmachines/inkling-small0.851$0.8958s
google/gemma-4-26b-a4b-it0.845$0.111002s

The Capable but Loose

12 models
strongbudgetprose-over-math12 fabrication-events
median mean 0.929median cost $0.90median latency 89sstrongest ops & maintenanceweakest reporting & analyticsfabrication events 12
Strong scores at budget prices, but this cluster carries fabrication events — models that invented a deal or company alias at least once. Correct on most work, but their output needs entity-validation guardrails before it touches production.
ModelMeanCostLat
z-ai/glm-5v-turbo0.967$1.81154s
tencent/hy30.967$0.331611s
z-ai/glm-5.10.964$1.99178s
openai/gpt-5.6-luna-pro0.943$1.0475s
deepseek/deepseek-v4-flash0.936$0.20151s
openai/gpt-5.4-mini0.935$3.2172s
stepfun/step-3.5-flash0.923$0.45166s
stepfun/step-3.7-flash0.919$0.791536s
openai/gpt-50.916$6.21131s
upstage/solar-pro40.913$0.0554s
qwen/qwen3.7-flash0.906$0.0883s
google/gemini-3-pro-image0.863$3.8066s

The Fast Communicators

7 models
weakbudgetfastprose-over-math
median mean 0.728median cost $0.43median latency 52sstrongest communicationweakest reporting & analyticsfabrication events 0
Budget, fast, prose-oriented. Comfortable writing digests and emails, weak on the heavy reporting math (weighted forecasts, rollforwards). Behavior profile: good words, shaky arithmetic — fit for drafts, not for numbers.
ModelMeanCostLat
inception/mercury-20.784$0.82746s
mistralai/ministral-14b-25120.755$0.4365s
inclusionai/ling-3.0-flash-fin0.745$0.15727s
nvidia/nemotron-3-nano-30b-a3b0.728$0.73133s
meta-llama/llama-4-maverick0.699$0.24151s
meta-llama/llama-3.3-70b-instruct0.683$0.0575s
upstage/solar-pro-30.645$0.69182s

The Speed Specialists

8 models
weakbudgetfastprose-over-math12 fabrication-events
median mean 0.742median cost $0.51median latency 18sstrongest ops & maintenanceweakest reporting & analyticsfabrication events 12
Ultra-fast budget models (median 18s) with mid-tier accuracy and fabrication risk in-cluster. Trade correctness for latency; usable where a quick pass beats a right pass, with validation.
ModelMeanCostLat
inception/mercury-2.5-preview0.868$0.1023s
mistralai/devstral-25120.791$0.6930s
nvidia/nemotron-3.5-lightning0.785$0.3222s
mistralai/ministral-3b-25120.741$0.2271s
mistralai/mistral-medium-3-50.739$1.49873s
mistralai/mistral-small-26030.711$0.139s
amazon/nova-premier-v10.698$10.09102s
amazon/nova-pro-v10.619$4.8148s

The Non-Functional

5 models
weakbudgetfastprose-over-math
median mean 0.124median cost $0.00median latency 29sstrongest communicationweakest customer & successfabrication events 0
Endpoints that returned instant garbage or refused to work ($0 cost, 3-6s responses). Not real scores — broken routes. Listed for completeness and exclusion.
ModelMeanCostLat
ibm-granite/granite-4.0-h-micro0.124$0.002s
minimax/minimax-m2-her0.124$0.0068s
thedrummer/cydonia-24b-v4.10.124$0.0046s
kwaipilot/kat-coder-pro-v20.111$0.0028s
kwaipilot/kat-coder-pro-v2.50.111$0.008s

Cost for Value — The Dollar Map

95 full-coverage models
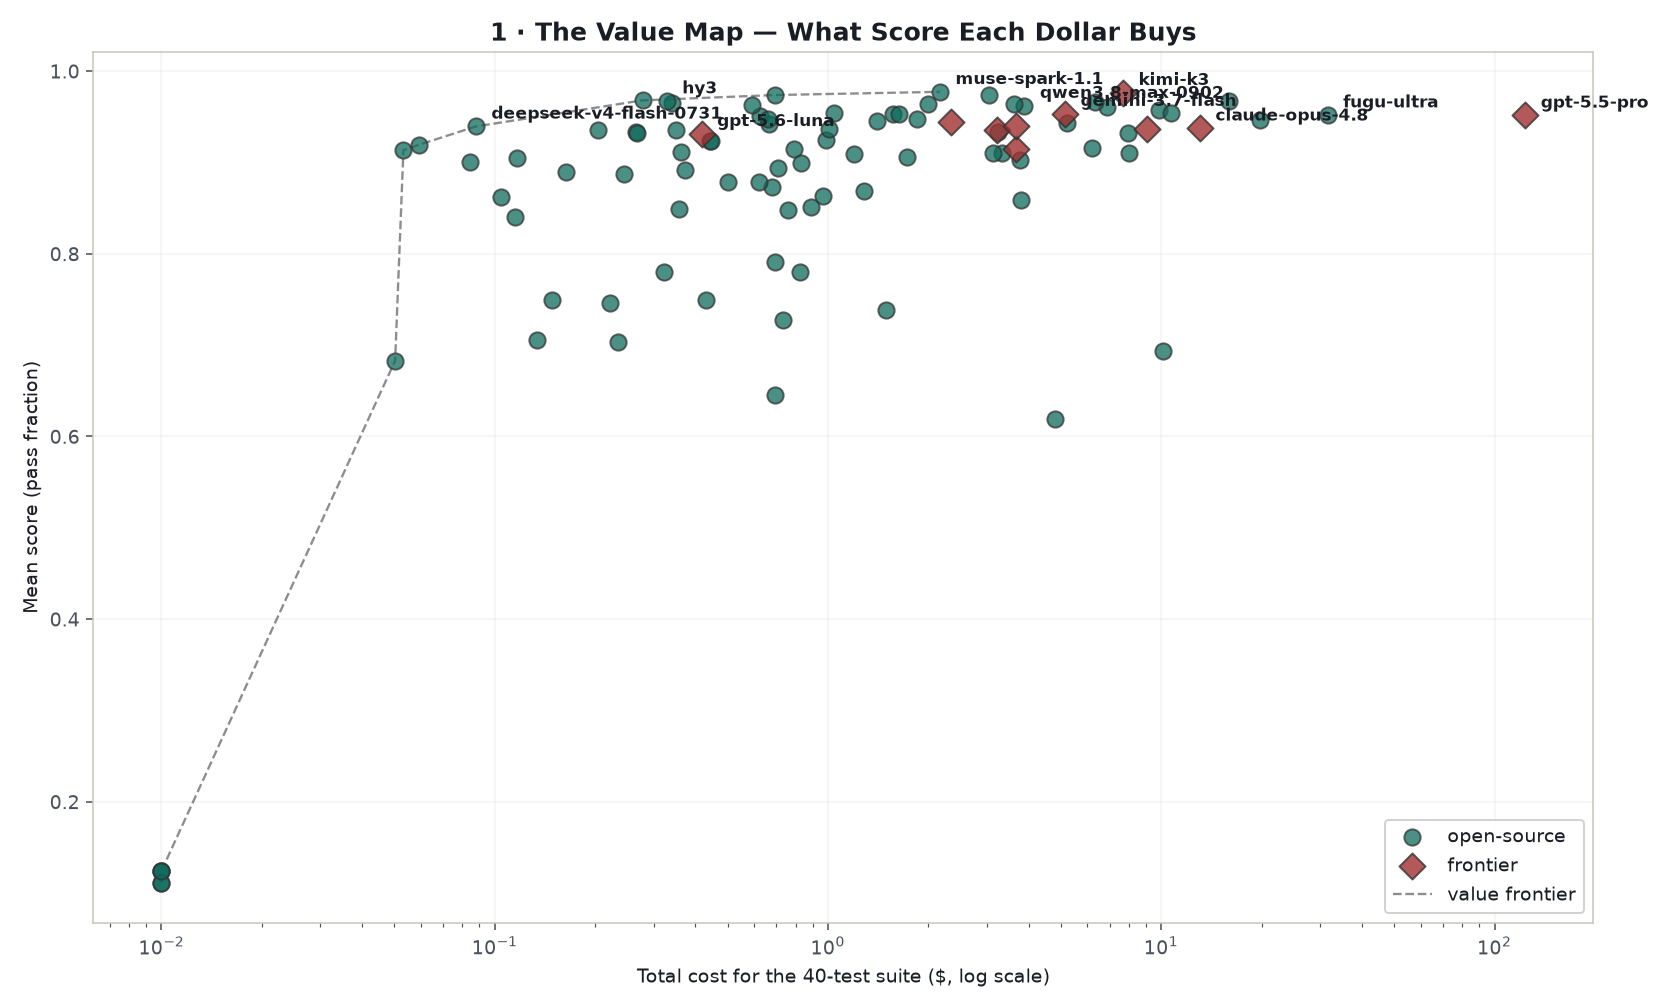
Where price and performance actually meet. $/point = total suite cost ÷ mean score — the price of one unit of benchmark performance. The value frontier is the pareto set: no model is both cheaper and better than these.

THE VALUE FRONTIER — cheapest at every score level

ModelMeanSuite Cost$/point
meta/muse-spark-1.10.977$2.17$2.22
xiaomi/mimo-v2.5-pro0.974$0.69$0.71
z-ai/glm-5.3-flash0.968$0.28$0.29
deepseek/deepseek-v4-flash-07310.939$0.09$0.09
inclusionai/ling-3.0-flash0.919$0.06$0.06
upstage/solar-pro40.913$0.05$0.06

VALUE KINGS — ≥0.93 mean at ≤$2 total (12 of 16 shown)

These models deliver top-decile scores for the price of a coffee. mimo-v2.5-pro, glm-5.3-flash, tencent/hy3, qwen3.8-flash all outscore every frontier model on this bench at under $0.75 each.
ModelMeanSuite Cost$/point
xiaomi/mimo-v2.5-pro0.974$0.69$0.71
z-ai/glm-5.3-flash0.968$0.28$0.29
tencent/hy3-preview0.968$0.59$0.61
tencent/hy30.967$0.33$0.34
qwen/qwen3.8-flash0.965$0.34$0.35
z-ai/glm-5.10.964$1.99$2.06
deepseek/deepseek-v4-pro0.959$1.04$1.09
meituan/longcat-2.00.955$0.63$0.66
moonshotai/kimi-k2.7-code0.953$1.57$1.64
qwen/qwen3.8-27b0.953$1.63$1.71
deepseek/deepseek-v4-pro-08130.947$1.85$1.96
openai/gpt-5.6-luna-pro0.943$1.04$1.11

EXCELLENT VALUE — strong scores at modest prices

ModelMeanSuite Cost$/point
meta/muse-spark-1.10.977$2.17$2.22
moonshotai/kimi-k30.976$7.67$7.86
meta/muse-spark-1.30.973$3.03$3.12
google/gemini-3.8-flash0.966$6.34$6.56
meta/muse-spark-1.20.964$3.60$3.74
qwen/qwen3.8-max-09020.962$3.88$4.04
z-ai/glm-5.30.960$6.86$7.14
google/gemini-3.7-flash0.953$5.14$5.39
anthropic/claude-haiku-4.50.944$2.34$2.47
openai/gpt-5.20.944$7.35$7.79

⚠ OVERPRICED — paid the premium, didn't cash it

High spend that the scores didn't justify. gpt-5.5-pro is the outlier of the entire exercise: $123.62 for the suite (129× the value kings' median) with a score below 16 models costing under $2. The premium tier's honest pitch is speed and vendor polish — on this bench, not accuracy.
ModelMeanSuite Cost$/point
openai/gpt-5.4-pro0.942$131.87$139.98
openai/gpt-5.5-pro0.956$123.62$129.26
openai/gpt-5.2-pro0.952$97.83$102.71
openai/gpt-5-pro0.927$93.00$100.31
openai/gpt-6-astra-pro0.941$43.54$46.26
Reading note: this is observed price-performance on these 40 tests, not a vendor verdict — list prices shift, and latency/SLA/enterprise features aren't priced here. The complete dollar map is in the Excel workbook and the value-map chart.